RETHINKING ATTENTION GATED WITH HYBRID DUAL PYRAMID TRANSFORMER-CNN FOR GENERALIZED SEGMENTATION IN MEDICAL IMAGING A PREPRINT
This paper presents a new method for segmenting medical images using a combination of CNNs and Transformers. The approach aims to improve the accuracy and efficiency of identifying different parts of medical images, which is important for diagnosis and treatment.
Content & Liability Disclaimer
This article and its accompanying video are automated summaries derived from RETHINKING ATTENTION GATED WITH HYBRID DUAL PYRAMID TRANSFORMER-CNN FOR GENERALIZED SEGMENTATION IN MEDICAL IMAGING A PREPRINT by Fares Bougourzi, Fadi Dornaika, Abdelmalik Taleb-Ahmed, Vinh Truong Hoang. The original research was conducted solely by the paper's authors; PDFdigest did not conduct any of the research and makes no claims of ownership over the underlying scientific work.
The video narration is generated by artificial intelligence and references the paper's authors for attribution. The video is not narrated by any of the paper's authors. This content may contain inaccuracies, omissions, or misinterpretations of the original research. First-person language (e.g., "we found", "our results") reflects the original authors' voice, not PDFdigest's. Always read the original paper for accurate, verified information before making any decisions based on this content.
This content is provided "as is" without any warranties, express or implied. Simulated systems OÜ, its officers, directors, employees, and agents shall not be liable for any direct, indirect, incidental, special, consequential, or punitive damages arising from your use of, reliance on, or access to this content, including but not limited to errors, omissions, or misinterpretations of the original research. This disclaimer applies to the fullest extent permitted by applicable law.
- 1 Numerous variants such as Attention U-Net, U-Net++, and ResU-Net have emerged to enhance segmentation performance.
- 2 These features are fed into a classic ViT Base with a patch size of 14 × 14 to produce 196 tokens.
- 3 The dataset contains 1517 slices, and we employed a five-fold cross-validation strategy to evaluate segmentation models.
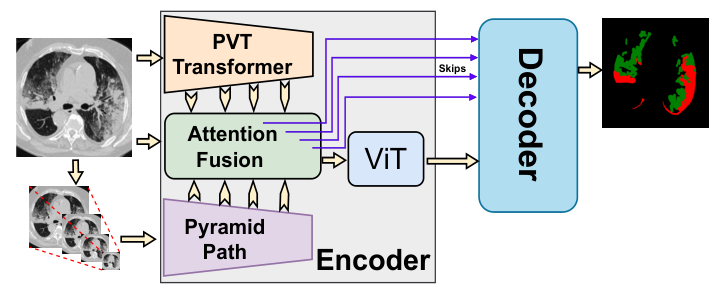
- 4 Existing architectures indicate limitations in efficiently combining transformer and CNN features by utilizing transformers as single or parallel encoders.
Introduction
Medical imaging segmentation aids in diagnosing, assessing severity, and monitoring progress in various medical conditions. Challenges persist in developing efficient machine learning approaches for medical imaging segmentation.
Limited labeled data availability presents a challenge because labeling is laborious and error-prone.
The goal is to devise a generalized approach for different medical segmentation tasks.
Limited labeled data availability presents a challenge because labeling is laborious and error-prone.
Transformer-based approaches exhibit limited generalization ability, achieving performance close to baseline CNN architectures.
Methodology
We conducted three iterations of five-fold cross-validation for each task following the proposed evaluation scheme. We compared our method with competing approaches and four recent transformer-based architectures for BM segmentation.
Study Design
This highlights our method’s capability to accurately highlight infection regions throughout all encoding blocks using Dual-Attention Gates.
Results & Findings
Existing architectures indicate limitations in efficiently combining transformer and CNN features by utilizing transformers as single or parallel encoders. This results in a more compact main path.
- Existing architectures indicate limitations in efficiently combining transformer and CNN features by utilizing transformers as single or parallel encoders.
- This results in a more compact main path.
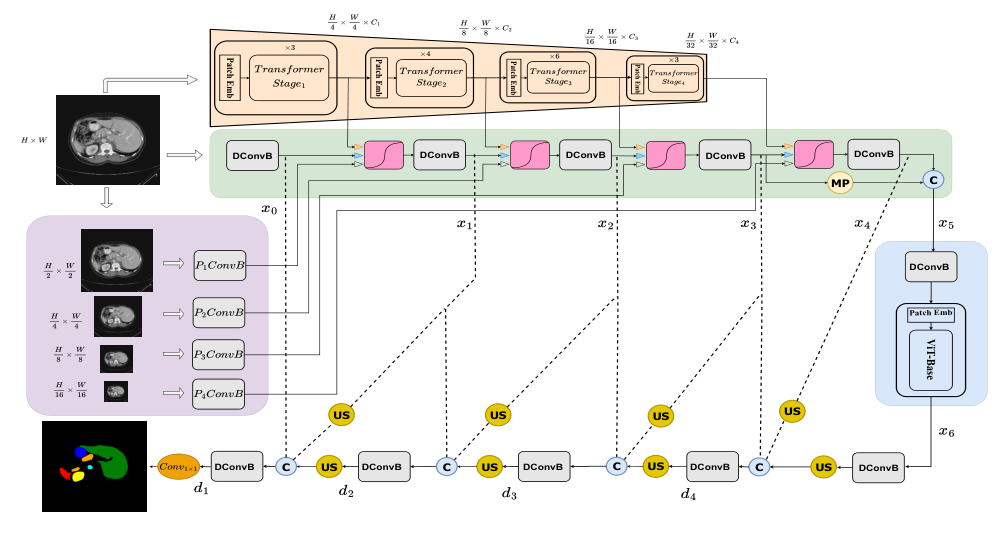
- These gates extract significant feature regions and merge features from both CNN and Transformer models.
- The first branch undergoes contraction through four pyramid levels using convolutional blocks to produce gating signals for the second branch.
- Features from the main branch highlight important features in the third branch, which utilizes Transformer architecture.
Numerous variants such as Attention U-Net, U-Net++, and ResU-Net have emerged to enhance segmentation performance.
These features are fed into a classic ViT Base with a patch size of 14 × 14 to produce 196 tokens.
How PDFdigest Helps You Understand Research
Instant Paper Analysis
Get structured summaries and key findings from dense PDFs in seconds.
Visual Explanations
Turn complex methods, figures, and results into clearer visual breakdowns.
AI-Powered Q&A
Ask focused questions and get answers grounded in the paper.
Proposed Approach
The proposed PAG-TransYnet architecture features a hybrid encoder with three branches and a U-Net-like decoder. It incorporates a Pyramid Vision Transformer and a Dual-Attention Gate mechanism to enhance feature extraction and integration.
PVT Transformer
This section details the Pyramid Vision Transformer (PVT) used in the proposed architecture, emphasizing its role in capturing long-range dependencies and enhancing segmentation performance.
Pyramid Encoder
The Pyramid Encoder provides convolutional features at multiple levels of the input image pyramid, utilizing spatial attention mechanisms to maintain awareness across encoder layers.
Source Paper Figures and Captions
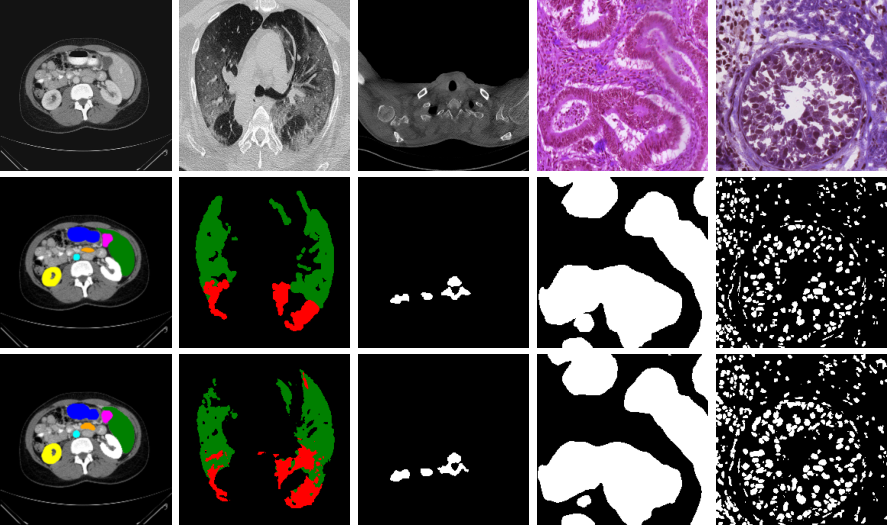
Illustrates the structure of the encoder and decoder components, highlighting the integration of CNN and Transformer features.
Provides a comprehensive view of the components and their interactions within the proposed segmentation architecture.
Demonstrates how pyramid levels are constructed and their role in feature extraction.
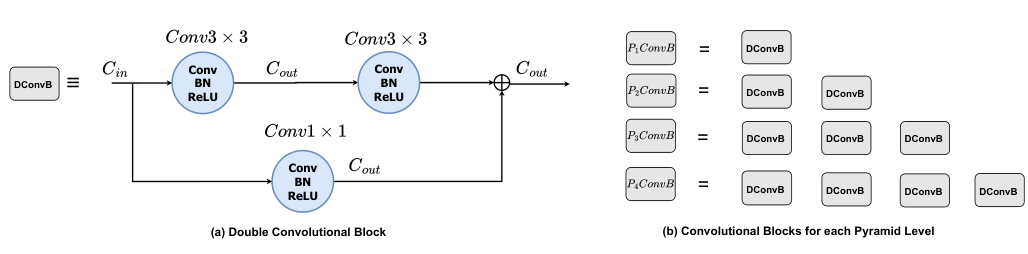
Explains the mechanism of the Dual-Attention Gate and its function in enhancing feature integration.
Frequently Asked Questions
The goal is to devise a generalized approach for different medical segmentation tasks. Many approaches are tailored to specific tasks, which limits their applicability to other tasks.
We conducted three iterations of five-fold cross-validation for each task following the proposed evaluation scheme. We compared our method with competing approaches and four recent transformer-based architectures for BM segmentation.
Numerous variants such as Attention U-Net, U-Net++, and ResU-Net have emerged to enhance segmentation performance. These features are fed into a classic ViT Base with a patch size of 14 × 14 to produce 196 tokens.
Limited labeled data availability presents a challenge because labeling is laborious and error-prone. Transformer-based approaches exhibit limited generalization ability, achieving performance close to baseline CNN architectures.
This paper presents a new method for segmenting medical images using a combination of CNNs and Transformers. The approach aims to improve the accuracy and efficiency of identifying different parts of medical images, which is important for diagnosis and treatment.
Yes. PDFDigest can turn this paper into a structured explanation, key takeaways, visual summaries, and a narrated video when available.