Exploring Hierarchy-Aware Inverse Reinforcement Learning
This paper presents a new approach to understanding how humans make decisions by using a model that considers the hierarchical nature of planning. It shows that this model can better predict human goals compared to traditional methods.
Use the local video fallback
Content & Liability Disclaimer
This article and its accompanying video are automated summaries derived from Exploring Hierarchy-Aware Inverse Reinforcement Learning by Chris J Cundy, Daniel Filan. The original research was conducted solely by the paper's authors; PDFdigest did not conduct any of the research and makes no claims of ownership over the underlying scientific work.
The video narration is generated by artificial intelligence and references the paper's authors for attribution. The video is not narrated by any of the paper's authors. This content may contain inaccuracies, omissions, or misinterpretations of the original research. First-person language (e.g., "we found", "our results") reflects the original authors' voice, not PDFdigest's. Always read the original paper for accurate, verified information before making any decisions based on this content.
This content is provided "as is" without any warranties, express or implied. Simulated systems OÜ, its officers, directors, employees, and agents shall not be liable for any direct, indirect, incidental, special, consequential, or punitive damages arising from your use of, reliance on, or access to this content, including but not limited to errors, omissions, or misinterpretations of the original research. This disclaimer applies to the fullest extent permitted by applicable law.
- 1 A Boltzmann-policy is optimal for an agent indifferent to actions that spends energy characterised by β to investigate high-reward actions.
- 2 IRL treats human behaviour as planning in a Markov decision process (MDP) to find a reward function explaining observed trajectories.
- 3 IRL aims to recover the reward function R from an observed trajectory in an MDP without R.
- 4 Previous work equips the taxi driver with hierarchical options like Go to x to show faster problem solving.
Introduction
We are increasingly aware of the limitations of goal specification as Reinforcement Learning (RL) algorithms become more capable. Hand-crafting goals for simple environments requires expert domain knowledge.
Value learning, or preference elicitation, involves algorithms learning goals by inferring human preferences.
Inverse optimal control or inverse reinforcement learning (IRL) is formalised by Ng & Russell and Abbeel & Ng.
Previous work modelled human actions as maximising utility subject to constraints like limited knowledge or inconsistent time preferences.
Recent work extends BIRL to incorporate non-optimal human behaviour like inconsistent time preferences or limited knowledge.
Research Question
A Boltzmann-policy is optimal for an agent indifferent to actions that spends energy characterised by β to investigate high-reward actions.
Methodology
We must develop a more robust method of goal specification to use AI for tasks beyond human abilities. A Bayesian method finds which trajectory parts correspond to each goal, but an arbitrarily parameterised reward function can model more tasks with less domain knowledge.
Study Design
We consider a realistic setting where the taxi driver has skills well-suited to the task but not optimal.
We use a simple MCMC method based on the Policy-Walk algorithm from Ramachandran & Amir.
How PDFdigest Helps You Understand Research
Instant Paper Analysis
Get structured summaries and key findings from dense PDFs in seconds.
Visual Explanations
Turn complex methods, figures, and results into clearer visual breakdowns.
AI-Powered Q&A
Ask focused questions and get answers grounded in the paper.
Results & Findings
IRL treats human behaviour as planning in a Markov decision process (MDP) to find a reward function explaining observed trajectories. We introduce a generative model of human decisions resulting from hierarchical planning using primitive actions and extended options.
- IRL treats human behaviour as planning in a Markov decision process (MDP) to find a reward function explaining observed trajectories.
- We introduce a generative model of human decisions resulting from hierarchical planning using primitive actions and extended options.
- We discuss the theoretical justification for this model and introduce a simple inference algorithm for hierarchically-generated trajectories.
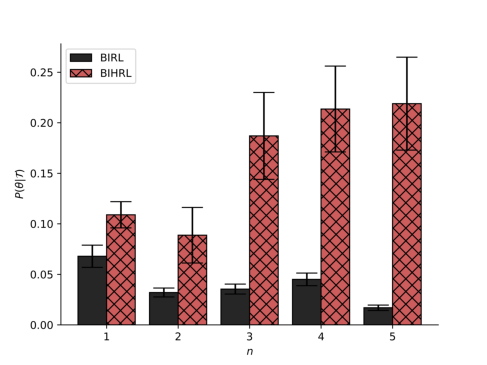
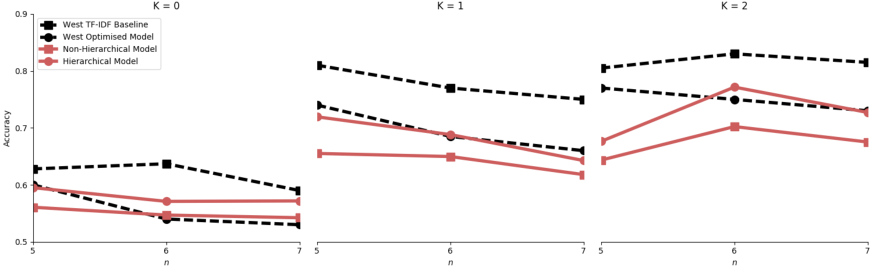
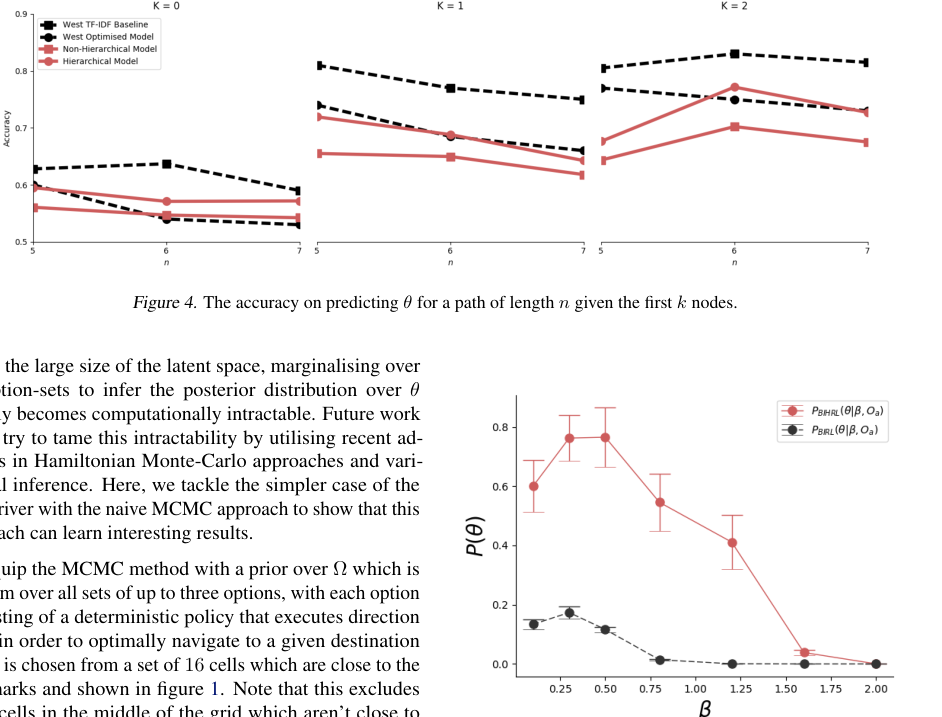
- Evaluating our model on ‘Wikispeedia’ game trajectories shows that hierarchical structure boosts goal prediction accuracy compared to standard Bayesian IRL.
- Our inference procedure can jointly infer options and preferences, retaining performance advantages over BIRL even without knowing the precise hierarchical structure.
We choose this model to combine planning at different abstraction levels with limited planning resources modelled by Boltzmann-rationality.
IRL treats human behaviour as planning in a Markov decision process (MDP) to find a reward function explaining observed trajectories.
Practical Applications
Humans do not choose between all physically possible trajectories. Humans might take available options instead of computing the optimal policy due to limited planning ability.
A person might choose a taxi or walking to cross a city because those skills have served them well.
They might not consider borrowing a bicycle even if it is faster and within their abilities.
Humans might take available options instead of computing the optimal policy due to limited planning ability.
Future work could utilise Hamiltonian Monte-Carlo and variational inference to tame this intractability.
Our Model
This section describes the Bayesian Inverse Hierarchical RL (BIHRL) model, detailing its components such as the MDP framework, stochastic policies, and the Boltzmann-rationality model. It explains how BIHRL incorporates hierarchical planning strategies to improve goal inference accuracy.
Source Paper Figures and Captions
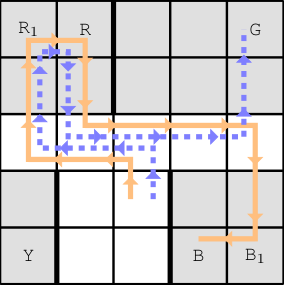
Illustrates the application of hierarchical options in modeling human decision-making in a specific scenario.
Frequently Asked Questions
A Boltzmann-policy is optimal for an agent indifferent to actions that spends energy characterised by β to investigate high-reward actions. Two trajectories are drawn from an agent with hierarchical options to go to R1 and B1.
We must develop a more robust method of goal specification to use AI for tasks beyond human abilities. We consider a realistic setting where the taxi driver has skills well-suited to the task but not optimal.
IRL treats human behaviour as planning in a Markov decision process (MDP) to find a reward function explaining observed trajectories. IRL aims to recover the reward function R from an observed trajectory in an MDP without R.
A person might choose a taxi or walking to cross a city because those skills have served them well. It is possible that very good models of human behaviour may be able to cut down the exponential numbers of human choices, by.
Humans might take available options instead of computing the optimal policy due to limited planning ability. We choose this model to combine planning at different abstraction levels with limited planning resources modelled by Boltzmann-rationality.
This paper presents a new approach to understanding how humans make decisions by using a model that considers the hierarchical nature of planning. It shows that this model can better predict human goals compared to traditional methods.