Benchmarking Neural Decoding Backbones towards Enhanced On-edge iBCI Applications
This paper explores how to improve brain-computer interfaces that can be used in everyday life by making them faster and more efficient. It compares different models to find the best one for processing brain signals on portable devices.
Content & Liability Disclaimer
This article and its accompanying video are automated summaries derived from Benchmarking Neural Decoding Backbones towards Enhanced On-edge iBCI Applications by Zhou Zhou, Guohang He, Zheng Zhang, Luziwei ⋆⋆, Leng, Qinghai Guo, Jianxing Liao, Xuan Song, Ran Cheng. The original research was conducted solely by the paper's authors; PDFdigest did not conduct any of the research and makes no claims of ownership over the underlying scientific work.
The video narration is generated by artificial intelligence and references the paper's authors for attribution. The video is not narrated by any of the paper's authors. This content may contain inaccuracies, omissions, or misinterpretations of the original research. First-person language (e.g., "we found", "our results") reflects the original authors' voice, not PDFdigest's. Always read the original paper for accurate, verified information before making any decisions based on this content.
This content is provided "as is" without any warranties, express or implied. Simulated systems OÜ, its officers, directors, employees, and agents shall not be liable for any direct, indirect, incidental, special, consequential, or punitive damages arising from your use of, reliance on, or access to this content, including but not limited to errors, omissions, or misinterpretations of the original research. This disclaimer applies to the fullest extent permitted by applicable law.
- 1 To the best of our knowledge, this work might be the first effort to investigate linear attention mechanisms in neural decoding, targeting fast and low-power inference on edge devices.
- 2 Models such as Receptance Weighted Key Value model (RWKV) and Selective State Space model (Mamba) have been designed utilizing linear attention mechanisms that offer reduced temporal and spatial complexity compared to traditional transformers.
- 3 The state space model is a mathematical framework used to describe the evolution of systems over time.
- 4 It employs state vectors to represent the current state of the system and uses state transition equations and observation equations to correlate the changes between system states and the relationship with observed data .
Introduction
Accurate decoding the brain activities is crucial for the success of these applications. Previous efforts have focused on employing adaptive filters such as Kalman Filters or traditional machine learning models such as Recurrent Neural Networks (RNNs) .
Neural decoding primarily relied on adaptive filters or traditional machine learning methods such as Kalman Filters , Wiener Filters or SVM .
Contemporary applications of brain decoding technologies extend to medical rehabilitation, assistive communication, and humancomputer interaction .
Given the limited variance in input data patterns, the data is processed through two separate attention heads.
Research Question
To the best of our knowledge, this work might be the first effort to investigate linear attention mechanisms in neural decoding, targeting fast and low-power inference on edge devices.
Methodology
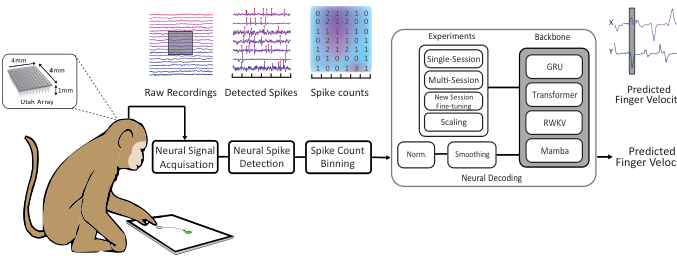
Models such as Neural Data Transformer (NDT1) leverage multi-session, multi-task and multi-subject neural data, yielding improved decoding performance and enhanced generalization capabilities with unseen data. Datasets The dataset from is used in this study, which includes a rich collection of neural and behavioral data recorded from nonhuman primates engaged in a random target reaching task.
Study Design
This task requires the subject controlling a ticker to move the computer cursor and reach a series of randomly distributed targets displayed on screen in succession.
During the execution of the task, the neural activities from primary motor cortex (M1) and primary sensory cortex (S1) are collected using Utah array, and the position of the subject’s hand kinematic trajectories are recorded using motion tracking systems.
How PDFdigest Helps You Understand Research
Instant Paper Analysis
Get structured summaries and key findings from dense PDFs in seconds.
Visual Explanations
Turn complex methods, figures, and results into clearer visual breakdowns.
AI-Powered Q&A
Ask focused questions and get answers grounded in the paper.
Results & Findings
Advancements in invasive Brain Computer Interfaces (iBCIs) have demonstrated promising results across various applications, including speech decoding , prosthesis control , neurological disorders rehabilitation and more. However, with the expansion of the available neural data, significant progress has been made using Transformer-based architectures.
- Advancements in invasive Brain Computer Interfaces (iBCIs) have demonstrated promising results across various applications, including speech decoding , prosthesis control , neurological disorders rehabilitation and more.
- However, with the expansion of the available neural data, significant progress has been made using Transformer-based architectures.
- Despite the advantages of RNNs for handling long-term dependency, their inherent serial dependency significantly affect the model’s inference speed .
- Meanwhile, it remains unclear whether scaling up GRU model size with data volume improves neural decoding accuracy.
- Transformers facilitate parallel computation and adhere to the scaling laws , but the increase in model size and sequence length leads to quadratic growth in model.
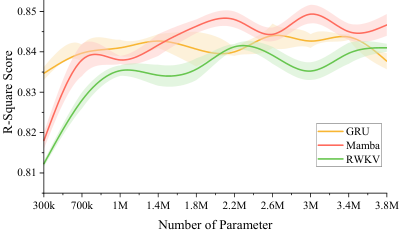
While performance gains for RWKV and Mamba level off as model size increases, this plateau is mainly attributable to the limited size of the current dataset.
These models have demonstrated competitive performance in natural language processing and computer vision tasks , but it remains unclear which model is most suitable as the backbone for neural decoding.
Practical Applications
Additionally, the design of the Transformer, which processes entire sequences simultaneously, may contribute to slower convergence rates during training. . Consequently, Mamba or RWKV could be suitable backbones for future neural decoding tasks, especially with an increasing amount of available neural recordings.
From a computational-saving perspective, instead of full parameter updating, tuning only the input and output layers or employing some transfer learning strategies might better accommodate input variations with less computational overhead.
Neural Decoding
Neural decoding has evolved with deep learning, improving accuracy and efficiency. The section outlines contemporary applications in medical rehabilitation and human-computer interaction.
Source Paper Figures and Captions
Frequently Asked Questions
To the best of our knowledge, this work might be the first effort to investigate linear attention mechanisms in neural decoding, targeting fast and low-power inference on edge devices. Transformer has precipitated as disruptive revolution, particularly due to its widespread application of.
Datasets The dataset from is used in this study, which includes a rich collection of neural and behavioral data recorded from nonhuman primates engaged in a random target reaching task. Additionally, the backbone models in this study were only trained on a.
Models such as Receptance Weighted Key Value model (RWKV) and Selective State Space model (Mamba) have been designed utilizing linear attention mechanisms that offer reduced temporal and spatial complexity compared to traditional transformers. The state space model is a mathematical framework used.
Additionally, the design of the Transformer, which processes entire sequences simultaneously, may contribute to slower convergence rates during training. . To explore whether increasing the model size could enhance its decoding performance, we examined the improvements achieved by increase the number of.
These models have demonstrated competitive performance in natural language processing and computer vision tasks , but it remains unclear which model is most suitable as the backbone for neural decoding. While performance gains for RWKV and Mamba level off as model size.
This paper explores how to improve brain-computer interfaces that can be used in everyday life by making them faster and more efficient. It compares different models to find the best one for processing brain signals on portable devices.